I have built LangChain agents for voice AI assistants, financial document Q&A systems, support ticket triage, and SaaS feature assistants. Every one of them looked great in the first demo. The production versions look almost nothing like those demos. The gap is not the model — it is the scaffolding: memory management, tool error handling, context window budgeting, structured logging, and graceful degradation. This is the guide I wish existed when I shipped my first production agent.
TL;DR — Production LangChain agents require explicit memory management, tool-level error handling, context window budgeting, and structured logging. Demos hide all of these. This guide exposes them.
The Right Agent Architecture for Production
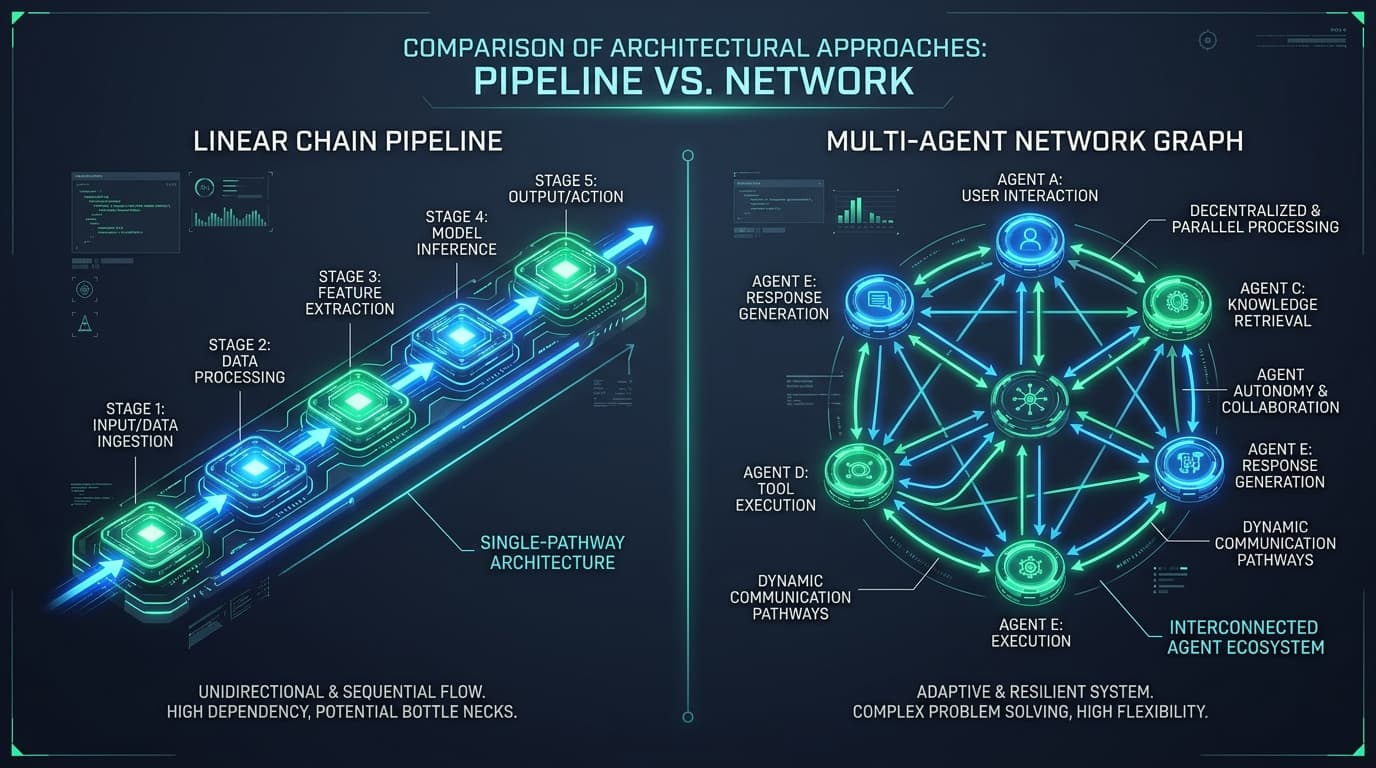
For most production use cases, I use OpenAI Tools agents (formerly function calling agents). They are more reliable than ReAct agents for tool use because the model returns structured tool call objects rather than parsing free-text 'Action: ...' outputs. Here is the base architecture I start from:
from langchain.agents import AgentExecutor, create_openai_tools_agent
from langchain_openai import ChatOpenAI
from langchain_core.prompts import ChatPromptTemplate, MessagesPlaceholder
from langchain_core.messages import SystemMessage
from langchain.memory import ConversationTokenBufferMemory

llm = ChatOpenAI(
    model="gpt-4o",
    temperature=0,
    max_retries=3,
    request_timeout=30,
)

memory = ConversationTokenBufferMemory(
    llm=llm,
    max_token_limit=6000,  # Budget context window explicitly
    memory_key="chat_history",
    return_messages=True,
)

prompt = ChatPromptTemplate.from_messages([
    SystemMessage(content=SYSTEM_PROMPT),
    MessagesPlaceholder("chat_history"),
    ("human", "{input}"),
    MessagesPlaceholder("agent_scratchpad"),
])

agent = create_openai_tools_agent(llm, tools, prompt)
executor = AgentExecutor(
    agent=agent,
    tools=tools,
    memory=memory,
    max_iterations=5,       # Hard cap on tool calls per turn
    handle_parsing_errors=True,
    verbose=True,
)Memory Management: The Part Everyone Gets Wrong
The default LangChain memory classes store every message indefinitely. In a long conversation, this burns through your context window and increases latency on every turn. In production, use ConversationTokenBufferMemory with an explicit token limit. I budget 6,000 tokens for history, which leaves 90,000+ tokens for the system prompt, tool outputs, and response on GPT-4o.
For multi-session agents (where conversations persist across logins), store history in PostgreSQL with a LangChain PostgresChatMessageHistory backend and load only the last N turns on each session start. Never load the full history unless you need it.
from langchain_community.chat_message_histories import PostgresChatMessageHistory

def get_session_memory(session_id: str, llm: ChatOpenAI) -> ConversationTokenBufferMemory:
    history = PostgresChatMessageHistory(
        connection_string=DATABASE_URL,
        session_id=session_id,
        table_name="agent_chat_history",
    )
    # Load only last 20 messages to prevent unbounded context growth
    history.messages = history.messages[-20:]

    return ConversationTokenBufferMemory(
        chat_memory=history,
        llm=llm,
        max_token_limit=6000,
        memory_key="chat_history",
        return_messages=True,
)Tool Error Handling That Doesn't Crash the Agent
Tools fail. APIs return 500s. Databases time out. The default behavior when a tool raises an exception is to crash the entire agent run. In production, you want the agent to receive the error as a tool output and decide what to do — usually retry with different parameters or tell the user it cannot complete the task right now.
from langchain.tools import tool
from langchain_core.tools import ToolException
import httpx
import structlog

logger = structlog.get_logger()

@tool
def search_knowledge_base(query: str) -> str:
    """Search the internal knowledge base for information about a topic.

    Args:
        query: The search query string

    Returns:
        Relevant passages from the knowledge base, or an error message
    """
    try:
        response = httpx.post(
            "http://kb-service/search",
            json={"query": query, "top_k": 5},
            timeout=10.0,
        )
        response.raise_for_status()
        results = response.json()["results"]
        if not results:
            return "No relevant information found for this query."
        return "\n\n".join(r["text"] for r in results)
    except httpx.TimeoutException:
        logger.error("knowledge_base_timeout", query=query)
        # Return error string — agent receives this and can decide to retry
        return "ERROR: Knowledge base search timed out. Try a shorter or more specific query."
    except httpx.HTTPStatusError as e:
        logger.error("knowledge_base_http_error", status=e.response.status_code, query=query)
        return f"ERROR: Knowledge base returned {e.response.status_code}. Cannot complete search right now."

# In AgentExecutor: handle_parsing_errors=True catches malformed tool calls
# Tool errors returned as strings let the agent reason about failuresStructured Logging for Observability
In production, you need to know: which tool calls happened, how long each took, what the inputs and outputs were, and which sessions are failing. I use structlog with a custom LangChain callback handler:
from langchain.callbacks.base import BaseCallbackHandler
import structlog
import time

logger = structlog.get_logger()

class ProductionLoggingCallback(BaseCallbackHandler):
    def __init__(self, session_id: str, user_id: str):
        self.session_id = session_id
        self.user_id = user_id
        self._tool_start_times: dict[str, float] = {}

    def on_tool_start(self, serialized, input_str, run_id=None, **kwargs):
        tool_name = serialized.get("name", "unknown")
        self._tool_start_times[str(run_id)] = time.time()
        logger.info("tool_call_start", tool=tool_name, input=input_str[:200],
                    session_id=self.session_id, user_id=self.user_id)

    def on_tool_end(self, output, run_id=None, **kwargs):
        duration = time.time() - self._tool_start_times.pop(str(run_id), time.time())
        logger.info("tool_call_end", output_length=len(str(output)),
                    duration_ms=round(duration * 1000),
                    session_id=self.session_id, user_id=self.user_id)

    def on_tool_error(self, error, run_id=None, **kwargs):
        logger.error("tool_call_error", error=str(error),
                     session_id=self.session_id, user_id=self.user_id)

    def on_agent_finish(self, finish, **kwargs):
        logger.info("agent_finish", output=finish.return_values.get("output", "")[:200],
                    session_id=self.session_id)

# Usage
executor.invoke(
    {"input": user_message},
    config={"callbacks": [ProductionLoggingCallback(session_id, user_id)]}
)Setting max_iterations and Handling Runaway Agents
Without max_iterations, a confused agent can loop indefinitely, burning tokens and money. I always set max_iterations=5 for customer-facing agents and max_iterations=10 for internal automation agents. When the limit is hit, AgentExecutor returns a partial result with a note that the agent stopped early — handle this in your API response.
Also set max_execution_time (in seconds) as a wall-clock backstop. If an agent is doing 5 tool calls that each take 8 seconds, you do not want to be blocked for 40 seconds on a customer-facing endpoint.
Need a LangChain AI agent built for your product? I ship production agents with proper memory, logging, and error handling. See prayagbagthariya.vercel.app/hire-me.
Frequently Asked Questions
What is the difference between LangChain OpenAI Tools agents and ReAct agents?
OpenAI Tools agents (create_openai_tools_agent) use the OpenAI function/tools API, where the model returns structured JSON tool calls. This is more reliable than ReAct agents, which parse free-text 'Action: tool_name' outputs using string regex — a fragile approach. For any production use case where tool calls need to be reliable, use the OpenAI Tools agent. ReAct is useful with non-OpenAI models that do not support the tools API.
How do I prevent a LangChain agent from using too many tokens?
Three levers: (1) ConversationTokenBufferMemory with an explicit max_token_limit to cap history size; (2) max_iterations on AgentExecutor to limit tool call rounds; (3) concise tool descriptions and return values — agents will include full tool outputs in their context, so truncate long tool responses before returning them. Also use gpt-4o-mini for classification and routing tasks, reserving gpt-4o for reasoning-heavy steps.
How do I give a LangChain agent access to a PostgreSQL database?
Build a @tool-decorated function that executes a parameterized query and returns results as a formatted string. Never pass raw user input into SQL — always use parameterized queries. For read-only agents, use a read-only database user. For write operations, add an explicit confirmation tool that the agent must call before executing a write, and log all write tool calls to an audit table.
Can I run LangChain agents asynchronously for better performance?
Yes — use AgentExecutor.ainvoke() instead of .invoke(). All LangChain OpenAI integrations support async natively. This matters on FastAPI endpoints where you want multiple agent requests to run concurrently. Make sure your tools are also async (use async def and httpx.AsyncClient instead of requests) to avoid blocking the event loop on I/O-heavy tool calls.
What should I log for LangChain agent observability in production?
At minimum: session_id, user_id, input, output, list of tool calls with their inputs and outputs, total token usage (from the LLM callback), and total duration. Use a custom BaseCallbackHandler to capture this. Ship logs to a structured sink (Datadog, Loki, CloudWatch Logs) with consistent field names so you can query 'all sessions where tool search_knowledge_base failed'. LangSmith is LangChain's hosted tracing product and adds a nice UI on top of the same data.
Continue reading
Get updates directly in your Google Search feed
Add this publication as a preferred source to highlight articles in Top Stories and AI Overviews.