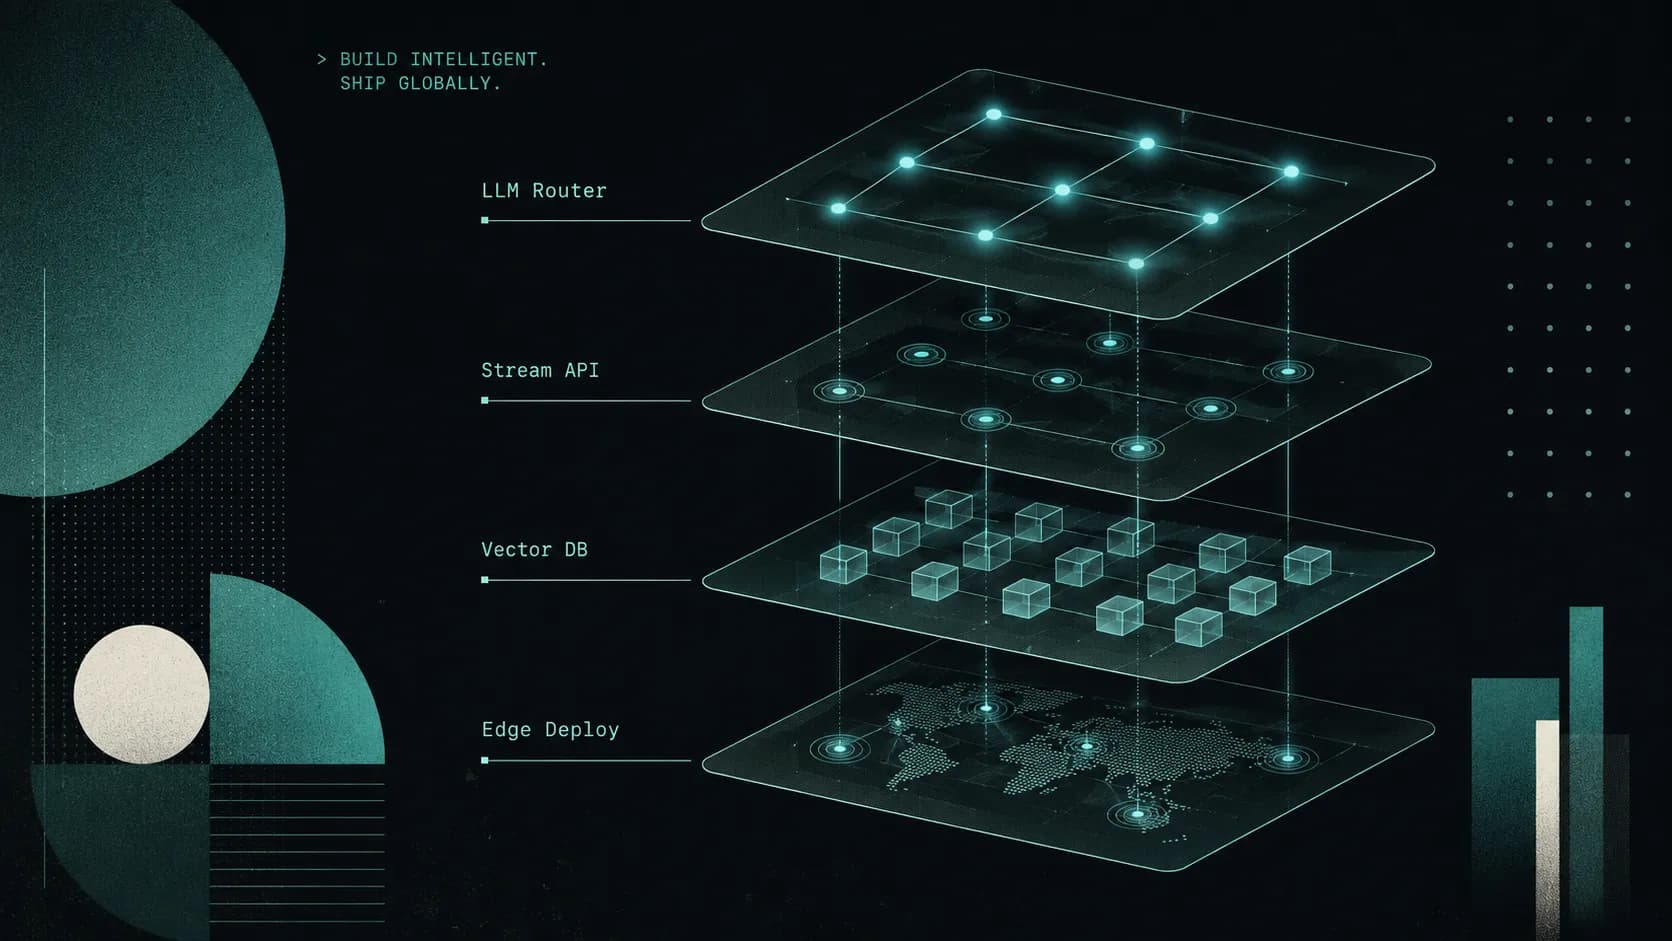
Every month a founder or a developer asks me some version of the same question: "What AI stack would you actually use?" Not "what's theoretically optimal" — what would I bet a client project on today. After shipping broken things in production and learning what breaks at 3am, I have a clear answer. Here it is.
TL;DR — Claude Sonnet 5 for reasoning tasks, GPT-4o-mini for high-volume cheap calls. Vercel AI SDK for streaming. pgvector over managed vector DBs until you hit 10M+ vectors. LangChain only for agents, raw SDK calls everywhere else. Vercel for deployment unless you need GPU inference, then Modal.
Layer 1: The LLM — Claude Sonnet 5 as Default, GPT-4o-mini for Volume
I default to Claude Sonnet 5 for any task that requires reasoning, instruction-following, or producing structured output. It follows complex system prompts more reliably than GPT-4o in my experience, and the context window is generous enough that I rarely need to chunk for anything short of full-codebase tasks.
For high-volume, cheap tasks — classifying support tickets, extracting metadata from form submissions, generating short summaries — I use GPT-4o-mini. It's fast, cheap, and good enough for simple extraction tasks. The mistake I see most teams make is using a frontier model for everything. You don't need Claude Sonnet 5 to detect whether a support email is billing-related or technical.
// Route different tasks to different models
const MODEL_ROUTING = {
  // Complex reasoning, long context, structured output
  reasoning: "claude-sonnet-5-20261101",
  // High-volume simple classification/extraction
  classification: "gpt-4o-mini",
  // User-facing chat (balance of quality + cost)
  chat: "claude-sonnet-5-20261101",
}

async function routedCompletion(task: keyof typeof MODEL_ROUTING, prompt: string) {
  const model = MODEL_ROUTING[task]
  if (model.startsWith("claude")) {
    return anthropic.messages.create({ model, max_tokens: 1024, messages: [{ role: "user", content: prompt }] })
  }
  return openai.chat.completions.create({ model, messages: [{ role: "user", content: prompt }] })
}Layer 2: The SDK — Vercel AI SDK, No Contest
I wasted two weeks building my own streaming abstraction before switching to the Vercel AI SDK. It handles streaming, tool calls, multi-model switching, and React hooks in a unified API. The useChat and useCompletion hooks alone save you a week of state management.
// app/api/chat/route.ts
import { streamText } from "ai"
import { anthropic } from "@ai-sdk/anthropic"

export async function POST(req: Request) {
  const { messages } = await req.json()

  const result = streamText({
    model: anthropic("claude-sonnet-5-20261101"),
    system: "You are a helpful assistant for a SaaS product.",
    messages,
    maxTokens: 2048,
  })

  return result.toDataStreamResponse()
}

// components/chat.tsx
import { useChat } from "ai/react"

export function Chat() {
  const { messages, input, handleInputChange, handleSubmit, isLoading } = useChat()

  return (
    <form onSubmit={handleSubmit}>
      {messages.map(m => <div key={m.id}>{m.content}</div>)}
      <input value={input} onChange={handleInputChange} disabled={isLoading} />
      <button type="submit">Send</button>
    </form>
  )
}
The one thing the Vercel AI SDK does not give you is observability. I add LangSmith or Helicone on top to trace every LLM call. Non-negotiable in production — you need to know when the model started hallucinating.
Layer 3: Vector Storage — pgvector Until You Actually Need More
Managed vector databases like Pinecone or Weaviate are genuinely great products. I also do not need them for any project under roughly 10 million vectors with moderate query traffic. pgvector running in the same Postgres instance I already have handles everything up to that scale, with zero extra infra cost and the ability to do hybrid SQL + semantic queries.
-- Enable pgvector and create an embeddings table
CREATE EXTENSION IF NOT EXISTS vector;

CREATE TABLE document_chunks (
  id          UUID PRIMARY KEY DEFAULT gen_random_uuid(),
  document_id UUID NOT NULL REFERENCES documents(id),
  content     TEXT NOT NULL,
  embedding   vector(1536),  -- OpenAI text-embedding-3-small dimensions
  metadata    JSONB DEFAULT '{}',
  created_at  TIMESTAMPTZ DEFAULT now()
);

-- HNSW index for fast approximate nearest-neighbour search
CREATE INDEX ON document_chunks
  USING hnsw (embedding vector_cosine_ops)
  WITH (m = 16, ef_construction = 64);

-- Hybrid search: semantic + keyword in one query
SELECT content, metadata,
       1 - (embedding <=> ${queryEmbedding}::vector) AS semantic_score,
       ts_rank(to_tsvector('english', content), plainto_tsquery(${query})) AS keyword_score
FROM document_chunks
ORDER BY (
  0.7 * (1 - (embedding <=> ${queryEmbedding}::vector)) +
  0.3 * ts_rank(to_tsvector('english', content), plainto_tsquery(${query}))
) DESC
LIMIT 5;
When you do outgrow pgvector — high write throughput, multi-tenant isolation per namespace, or billions of vectors — then Pinecone Serverless is where I'd go. But that is a scaling problem, not a starting problem.
Layer 4: Orchestration — Raw SDK Calls First, LangChain Only for Agents
I have a strong opinion here: LangChain is the right tool for multi-step agents with tool use and memory. It is not the right tool for a simple RAG pipeline or a single completion call. I have ripped LangChain out of three projects where it was used as a glorified fetch wrapper. The abstraction cost is real — debugging a LangChain chain is significantly harder than debugging three lines of SDK code.
- Single LLM call → raw Anthropic/OpenAI SDK, 3 lines of code
- RAG retrieval + generation → write it yourself, it's 50 lines
- Multi-step agent with tool calls, memory, and retry logic → LangChain is worth it
- n8n for workflow automation that non-engineers need to modify
Layer 5: Deployment — Vercel for Everything, Modal for GPU Inference
I deploy Next.js AI apps on Vercel. The Edge Runtime is excellent for streaming LLM responses and the DX is unbeatable. The one limitation is the 60-second function timeout on the Pro plan — for long-running AI tasks I either stream the response incrementally or move the heavy processing to a background job via a queue.
If you need to run your own models — Llama 3, Whisper, a fine-tuned embedding model — Modal is the best option I've found. Cold start times are reasonable, pricing is per-second, and you can deploy a GPU function in the same commit as your Next.js app.
The Full Stack at a Glance
- LLM: Claude Sonnet 5 (reasoning/chat) + GPT-4o-mini (classification/volume)
- SDK: Vercel AI SDK with useChat hook
- Observability: Helicone or LangSmith on every LLM call
- Vector storage: pgvector in existing Postgres (Pinecone at scale)
- Orchestration: raw SDK calls for simple, LangChain for agents
- Automation workflows: n8n self-hosted or n8n Cloud
- Deployment: Vercel (app) + Modal (self-hosted model inference)
- Database: Supabase (Postgres + pgvector + Auth in one)
Building a SaaS and need an AI stack that actually ships? I work with early-stage and growing teams to design, build, and deploy production AI features. → prayagbagthariya.vercel.app/hire-me
Frequently Asked Questions
Should I build with one LLM provider or support multiple?
Start with one. Multi-provider abstractions add real complexity and you will not need them until you have a cost or reliability problem. Build with Claude or OpenAI, ship, and abstract later if a specific provider starts causing issues. The Vercel AI SDK makes switching providers a one-line change when the time comes.
Is pgvector production-ready for RAG?
Yes, for the vast majority of applications. It handles millions of vectors with sub-100ms query times when you add an HNSW index. The advantage over managed vector DBs is that you can do hybrid SQL + semantic queries in a single round trip, join against your existing data model, and run transactions. The disadvantage is you manage the Postgres instance yourself.
How do I handle LLM costs as my SaaS scales?
Route tasks to the cheapest model that can handle them (GPT-4o-mini for simple tasks, frontier models for complex ones). Cache embeddings aggressively — recompute them only when content changes. Use prompt caching when your provider supports it (Anthropic offers cache_control for long system prompts). Set hard token limits per user per day and expose a usage dashboard so users can see their consumption.
When should I consider fine-tuning instead of prompt engineering?
Fine-tune when you have at least 50-100 high-quality examples of the exact output format you need, the task is repetitive and well-defined, and latency or cost is a concern (fine-tuned smaller models can outperform larger base models on specific tasks). For most early-stage SaaS products, prompt engineering with few-shot examples gets you 90% of the way there without the training cost and maintenance burden.
What monitoring should I set up for an AI SaaS from day one?
Log every LLM call: model, input tokens, output tokens, latency, and cost. Track user-level usage to catch abuse early. Set up alerts for error rate spikes (often a sign of prompt injection or model API issues). Monitor your vector search latency — pgvector queries can degrade as your index grows if you don't tune ef_search. And track business metrics alongside AI metrics: are users actually using the AI features, and are those users retaining better?
Continue reading

Why "Vibe Coding" Feels Like Flying Until You Hit Production: A Brutally Honest Field Guide for 2026
Why Insurtech Still Runs on Java: What Building US Retirement Engines Taught Me About Architecture, Rust, and Why India Got It Right
Get updates directly in your Google Search feed
Add this publication as a preferred source to highlight articles in Top Stories and AI Overviews.